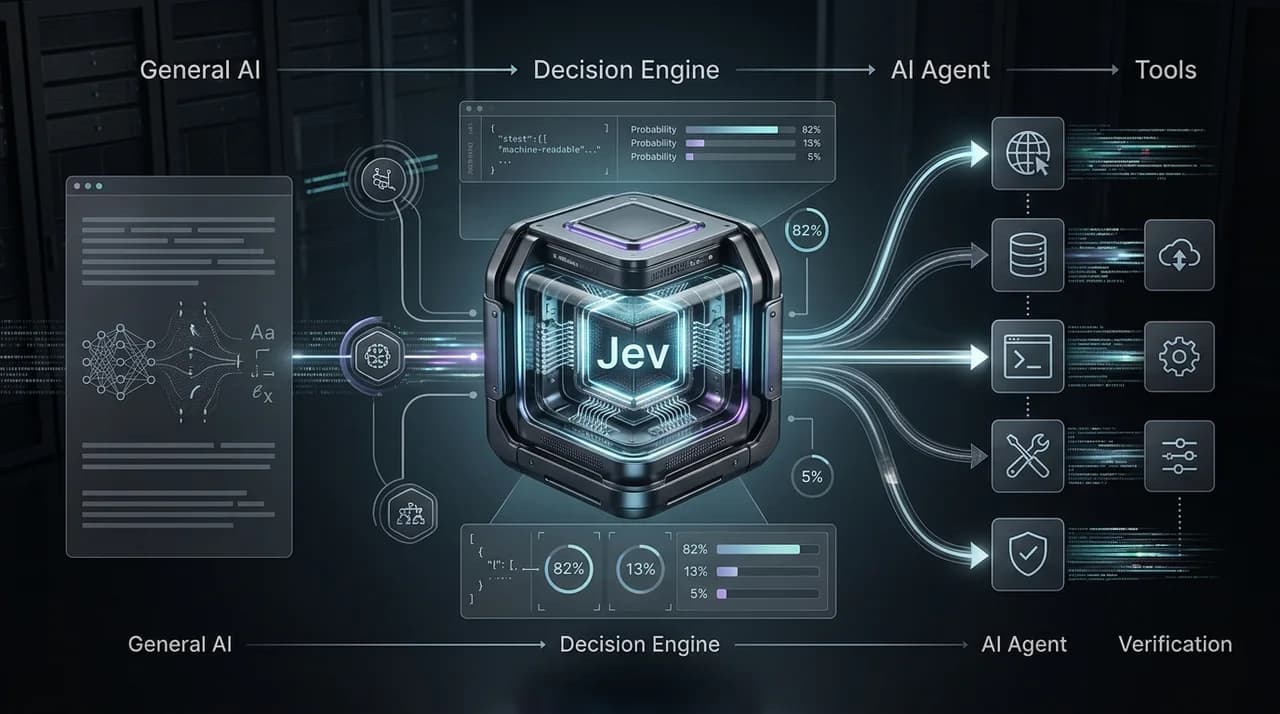
NVIDIA has recently introduced the Nemotron 3.5 Lightning, a cutting-edge AI model specifically designed to cater to the needs of long-running agents that engage in high-volume task execution. This innovative model leverages a 30 billion mixture-of-experts (MoE) architecture, featuring 3 billion active parameters, to optimize the execution layer for various tasks including tool calls and result validation. This advancement marks a significant step forward in the realm of artificial intelligence, particularly in enhancing the efficiency and effectiveness of AI agents.
Understanding the Need for Optimization
As artificial intelligence continues to evolve, the demand for efficient execution in AI agents becomes increasingly critical. Long-running AI agents often spend a significant amount of their operational time on tasks that require substantial computational resources, such as tool calls and subagent delegation. These tasks are vital for ensuring that AI systems can function effectively in real-world applications, but they can also introduce unnecessary costs and latency during execution.
Traditional reasoning models, while effective in many scenarios, can struggle to keep pace with the growing complexity and volume of tasks that AI agents are expected to handle. As a result, there is a pressing need for models that not only enhance performance but also optimize resource utilization. The Nemotron 3.5 Lightning addresses this need by providing a more agile and responsive framework for AI task execution.
NVIDIA's Innovative Approach
The Nemotron 3.5 Lightning addresses these challenges by employing a mixture-of-experts model. This architecture allows the system to dynamically select the most relevant subset of its 30 billion parameters, thus optimizing performance and resource utilization. With 3 billion active parameters specifically tuned for execution tasks, this model aims to reduce the time and computational power needed for AI agents to function effectively.
By utilizing a mixture-of-experts framework, the model can activate only the necessary components required for a specific task, leading to significant reductions in latency and operational costs. This targeted approach not only enhances the speed at which AI agents can perform tasks but also ensures that they do so with a level of precision that is critical in high-stakes environments.
Key Features of Nemotron 3.5 Lightning
- Mixture-of-Experts Model: The 30 billion MoE architecture enhances the model's ability to manage complex task execution, allowing for a more tailored approach to AI operations.
- Active Parameters: With 3 billion active parameters, the model is finely tuned for high-volume execution scenarios, ensuring that it can handle a wide array of tasks efficiently.
- Reduced Latency: By optimizing the execution layer, Nemotron 3.5 Lightning minimizes latency, enabling faster responses that are crucial for real-time applications.
- Cost Efficiency: The model aims to lower operational costs associated with traditional reasoning models, making it an attractive option for businesses looking to leverage AI without incurring prohibitive expenses.
Applications in Real-World Scenarios
The advancements offered by Nemotron 3.5 Lightning are particularly relevant for industries that rely heavily on AI agents for ongoing operations. Sectors such as customer service, where AI chatbots handle inquiries and support requests, can benefit from the model's enhanced performance and reliability. Similarly, in data analysis, the ability to quickly process and analyze large datasets can lead to more informed decision-making.
Moreover, automated decision-making processes can be significantly improved with the introduction of this model. By reducing latency and enhancing the accuracy of task execution, organizations can streamline their operations and respond more effectively to dynamic market conditions. This capability is especially important in fast-paced industries where timely decisions can lead to competitive advantages.
Conclusion: A Step Forward in AI Technology
NVIDIA's Nemotron 3.5 Lightning represents a significant leap forward in AI technology, particularly for long-running agents. By addressing the inherent challenges of traditional execution models, this new offering not only enhances performance but also paves the way for more sophisticated and efficient AI applications. As organizations increasingly adopt AI solutions, models like Nemotron 3.5 Lightning will be crucial in meeting the demands of high-volume task execution.
Looking Ahead
As AI technology continues to evolve, the focus on optimizing execution layers will likely become even more pronounced. NVIDIA's commitment to innovation in this space suggests that we can expect further advancements that will enhance the functionality and efficiency of AI agents. The introduction of the Nemotron 3.5 Lightning is just one example of how the industry is progressing towards more capable and responsive AI systems.
In conclusion, the future of AI is not just about creating more powerful models but also about creating smarter, more efficient systems that can adapt to the needs of users and industries. The Nemotron 3.5 Lightning is a testament to this vision, setting a new standard for what is possible in AI-driven task execution.
Key Highlights
- NVIDIA's Nemotron 3.5 Lightning is designed for long-running AI agents.
- The model features a 30 billion mixture-of-experts architecture.
- It optimizes execution tasks such as tool calls and result validation.
- 3 billion active parameters are specifically tuned for high-volume execution.
- The model aims to reduce costs and latency associated with traditional models.
- Applications span various industries, enhancing operational efficiency.
- The introduction of this model marks a significant advancement in AI technology.
Expert Analysis
Technical Analysis
The NVIDIA Nemotron 3.5 Lightning utilizes a mixture-of-experts (MoE) architecture, which is designed to enhance the efficiency of AI agents engaged in high-volume task execution. This model incorporates a staggering 30 billion parameters, of which 3 billion are actively utilized for specific execution tasks. The MoE framework allows the system to dynamically select the most relevant parameters for a given task, optimizing both performance and resource utilization. This targeted approach is particularly beneficial for tasks that require significant computational resources, such as tool calls and subagent delegation, which are common in real-world applications.
The primary problem that the Nemotron 3.5 Lightning addresses is the latency and operational costs associated with traditional AI reasoning models. By reducing the time and computational power needed for AI agents to perform tasks, this model not only enhances speed but also maintains a high level of precision. However, while the MoE architecture offers significant improvements in efficiency, it may also introduce complexities in model management and require careful tuning to ensure optimal performance across diverse tasks.
Advantages
- Enhanced performance for long-running AI agents, improving task execution efficiency.
- Dynamic parameter selection reduces latency, enabling faster responses for real-time applications.
- Cost-efficient model that lowers operational expenses compared to traditional reasoning models.
- Scalability in handling complex tasks due to the 30 billion parameter architecture.
Disadvantages
- No major disadvantages reported yet.
Real-World Use Cases
- Customer service applications where AI chatbots can handle inquiries more efficiently.
- Data analysis tasks that require quick processing of large datasets for informed decision-making.
- Automated decision-making processes that benefit from reduced latency and enhanced accuracy.
- Industries requiring real-time responses to dynamic market conditions, such as finance or logistics.
Business Impact
The introduction of the Nemotron 3.5 Lightning is likely to create a significant impact in industries that rely heavily on AI, particularly in sectors like customer service and data analysis. By optimizing task execution, businesses can achieve greater efficiency and cost savings, which may lead to increased adoption of AI solutions. Competitors in the AI space will need to respond to this advancement, potentially accelerating innovation and improvements across the industry as they seek to match or exceed the capabilities offered by NVIDIA's latest model.
User Impact
Ordinary users, particularly those in customer service or data-driven industries, stand to benefit from the enhanced performance and reliability of AI applications powered by the Nemotron 3.5 Lightning. While the technical improvements may not be directly visible to end-users, the resulting efficiency and speed in AI interactions can significantly enhance user experience. As businesses adopt this technology, it is likely to become a standard offering, making it worthwhile for organizations to consider integrating such advanced AI solutions into their operations.
Security & Privacy
Security and privacy analysis not applicable.
Future Outlook
As the demand for efficient AI solutions continues to grow, NVIDIA's focus on optimizing execution layers suggests that we can expect further advancements in the field. Future developments may include enhancements in the MoE architecture or new features that further reduce latency and improve resource management. This trend towards smarter, more efficient AI systems is likely to shape the direction of the industry, pushing competitors to innovate and adapt to maintain relevance in a rapidly evolving landscape.
Expert Summary
The unveiling of NVIDIA's Nemotron 3.5 Lightning is a notable advancement in AI technology, particularly for applications requiring high-volume task execution. Organizations looking to enhance their AI capabilities should pay attention to this development, as it sets a new standard for efficiency and performance in AI agents. Overall, this model represents a significant step forward in addressing the challenges faced by traditional AI systems, making it a critical consideration for businesses aiming to leverage AI effectively.
Originally reported by NVIDIA Technical Blog.