In the rapidly evolving field of artificial intelligence, optimizing large language model (LLM) inference is crucial for developers and researchers. NVIDIA's latest blog post dives into the innovative concept of speculative decoding, which promises to enhance the speed of LLM inference while maintaining accuracy. This article is part of a series on AI model co-design, and it presents practical guidelines for balancing throughput and interactivity.
Understanding Speculative Decoding
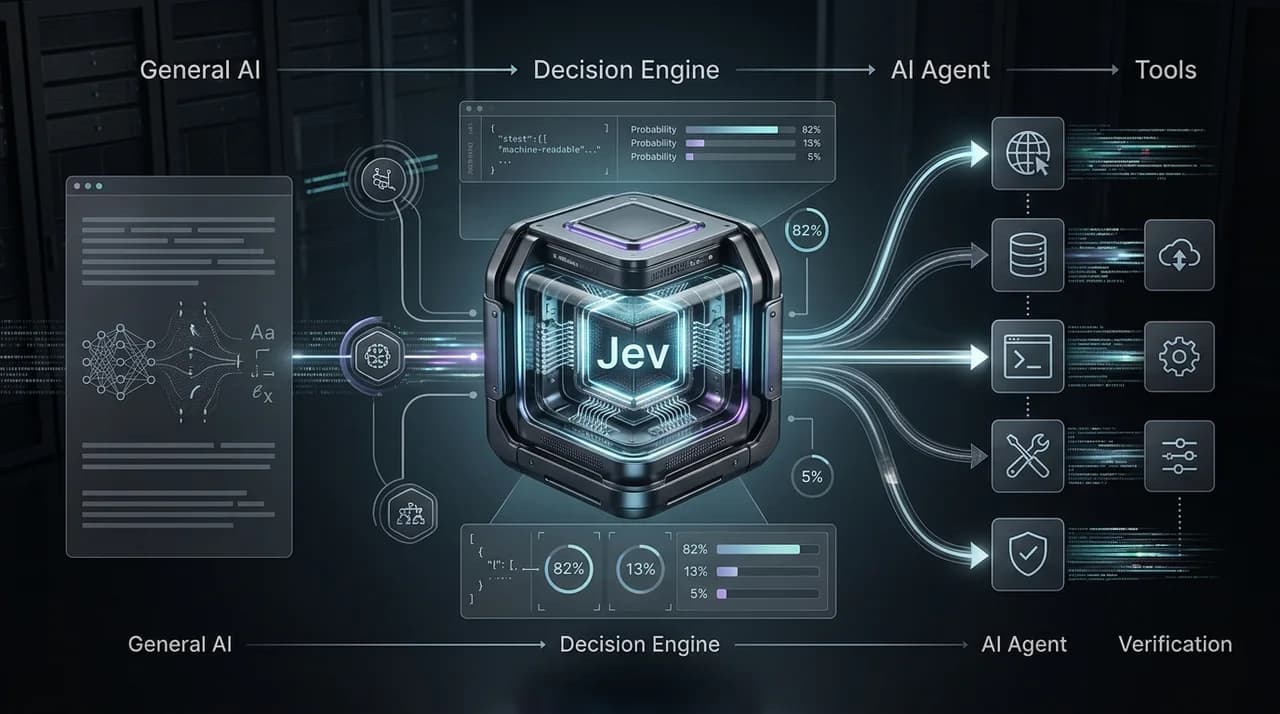
Speculative decoding is an advanced technique that allows AI models to predict and generate outputs more efficiently. By leveraging this method, developers can significantly reduce the time it takes for models to produce results. The essence of speculative decoding lies in its ability to make educated guesses about the next words or phrases in a sequence, which can lead to faster inference times without compromising the quality of the output.
This approach is particularly relevant in the context of LLMs, which are increasingly being used in applications ranging from chatbots to content generation. As these models grow in complexity and size, the demand for efficient inference mechanisms becomes more pressing. Speculative decoding addresses this need by enabling models to generate outputs in a more streamlined manner, effectively predicting the most likely continuations of a given text.
Importance of Draft Length and Mechanism
The blog outlines five essential guidelines for selecting the appropriate draft length and draft mechanism when implementing speculative decoding. These guidelines are vital for navigating the trade-offs between speed and accuracy. Finding the right draft length is particularly important; too short may lead to incomplete outputs, while too long can hinder performance.
Draft length plays a critical role in the overall performance of LLMs. A shorter draft may result in outputs that are abrupt or lack context, potentially confusing users. Conversely, a longer draft can slow down the inference process, negating the benefits of speculative decoding. Hence, developers must carefully evaluate the needs of their specific applications to determine the optimal draft length.
Guidelines for Effective Co-Design
- Assess the Application Needs: Understand the specific requirements of your application to tailor the draft length accordingly. Different applications may have varying tolerances for speed and accuracy, making this assessment crucial.
- Optimize for Throughput: Aim for a draft length that maximizes throughput without sacrificing the quality of generated text. This ensures that the model can handle a high volume of requests efficiently.
- Balance Interactivity: Ensure that the model remains responsive to user inputs while maintaining accuracy in its outputs. Users expect real-time feedback, especially in interactive applications.
- Test Various Mechanisms: Experiment with different draft mechanisms to identify the most effective approach for your use case. Different mechanisms may yield different results in terms of speed and accuracy.
- Iterate on Feedback: Use real-world feedback to fine-tune the draft parameters and improve overall model performance. Continuous iteration based on user feedback can lead to significant enhancements over time.
Balancing Throughput and Interactivity
One of the challenges in AI model co-design is achieving a balance between throughput and interactivity. Speculative decoding offers a promising solution, but it requires careful consideration of how these elements interact. Developers must ensure that while they push for faster outputs, the model remains capable of engaging users effectively.
Throughput refers to the amount of data processed in a given time frame, while interactivity pertains to the model's ability to respond to user inputs in a timely manner. Striking the right balance between these two aspects is essential for creating a seamless user experience. For instance, in applications such as virtual assistants or customer support bots, users expect quick and relevant responses. If the model prioritizes speed at the expense of accuracy, it may lead to user frustration and decreased trust in the system.
Maintaining Accuracy in AI Models
While speed is essential, maintaining accuracy is equally critical. The guidelines presented emphasize that developers should not compromise on the correctness of the generated text. Speculative decoding can enhance speed, but it must be implemented in a way that does not degrade the model's reliability. This balance is crucial for applications where precision is paramount.
In fields such as healthcare or legal services, for example, the implications of inaccurate outputs can be severe. Therefore, developers must implement rigorous testing and validation processes to ensure that the outputs generated by the model meet the required standards of accuracy. This may involve using benchmark datasets and performance metrics to evaluate the model's effectiveness in real-world scenarios.
Looking Ahead in AI Model Co-Design
As the field of AI continues to advance, the integration of techniques like speculative decoding will play a vital role in shaping the future of LLMs. NVIDIA's insights into co-design methodologies provide valuable frameworks for developers looking to optimize their models. By adhering to the guidelines discussed, practitioners can harness the full potential of their AI systems while ensuring user satisfaction and output quality.
Moreover, as AI applications become more ubiquitous, the need for efficient and accurate LLMs will only grow. The ability to generate high-quality text quickly will be a competitive advantage for businesses and developers alike. Therefore, investing in understanding and implementing speculative decoding and other advanced techniques will be essential for staying ahead in the rapidly evolving AI landscape.
Conclusion
In conclusion, the exploration of speculative decoding in NVIDIA's blog highlights an important step forward in AI model co-design. By focusing on effective draft length and mechanisms, developers can achieve faster inference times without sacrificing accuracy. This approach not only enhances the performance of LLMs but also sets the stage for more interactive and responsive AI applications in the future. As the landscape of artificial intelligence continues to evolve, embracing innovative techniques like speculative decoding will be vital for developers aiming to create robust and efficient AI systems.
Key Highlights
- Speculative decoding enhances the speed of LLM inference while maintaining accuracy.
- Five guidelines help developers choose optimal draft lengths and mechanisms.
- Balancing throughput and interactivity is crucial for effective AI applications.
- Real-world feedback is essential for refining AI model performance.
- Maintaining accuracy is as important as achieving faster outputs in AI models.
Expert Analysis
Technical Analysis
Speculative decoding is an advanced technique in artificial intelligence that enhances the efficiency of large language model (LLM) inference. It operates by allowing AI models to predict the next words or phrases in a sequence, effectively generating outputs more quickly while maintaining accuracy. This method addresses the growing demand for faster inference times as LLMs become more complex and are increasingly utilized in applications such as chatbots and content generation. By making educated guesses about potential continuations, speculative decoding streamlines the output generation process, thus reducing latency without compromising the quality of the results.
The implementation of speculative decoding involves careful consideration of draft length and mechanisms. Developers must navigate the trade-offs between speed and accuracy, as a draft that is too short may produce incomplete outputs, while one that is too long could hinder performance. The guidelines provided in the article emphasize the importance of assessing application needs, optimizing for throughput, balancing interactivity, testing various mechanisms, and iterating based on user feedback. While speculative decoding presents a promising solution for enhancing LLM performance, it also requires rigorous testing and validation to ensure that accuracy is not sacrificed for speed.
Advantages
- Increases the speed of LLM inference, allowing for quicker output generation.
- Maintains accuracy in generated text, which is crucial for user trust and application reliability.
- Provides guidelines for optimizing draft length, enhancing overall model performance.
- Facilitates a balance between throughput and interactivity, improving user experience in applications.
Disadvantages
- No major disadvantages reported yet.
Real-World Use Cases
- Developers can implement speculative decoding in chatbots to provide faster and more accurate responses to user queries.
- Content generation applications can leverage this technique to enhance the speed of producing high-quality text.
- Virtual assistants can utilize speculative decoding to improve responsiveness while ensuring the accuracy of information provided.
Business Impact
The introduction of speculative decoding is likely to have a significant impact on the AI market, as businesses increasingly seek efficient and accurate LLMs to enhance their services. Companies that adopt this technology may gain a competitive edge by offering faster and more reliable AI-driven solutions. As the demand for interactive applications grows, the ability to implement advanced techniques like speculative decoding will open new revenue opportunities and drive innovation across various industries.
User Impact
Ordinary users will benefit from the enhanced responsiveness and accuracy of AI applications that utilize speculative decoding. This improvement is particularly relevant in customer service and content generation, where timely and relevant responses are expected. However, users may not be aware of the underlying technology; their primary concern will be the quality of the interactions they have with AI systems. Overall, the adoption of this technology is likely to enhance user satisfaction and trust in AI applications.
Security & Privacy
Security and privacy analysis not applicable.
Future Outlook
In the near term, we can expect further advancements in AI model co-design techniques, including the refinement of speculative decoding. As developers continue to explore its potential, improvements in both speed and accuracy are anticipated, leading to more robust AI applications. The industry direction suggests a growing emphasis on user experience, where the balance between throughput and interactivity will become increasingly critical as AI systems evolve.
Expert Summary
The exploration of speculative decoding in NVIDIA's latest blog is a significant development in the optimization of AI model co-design. Developers and businesses focused on enhancing the performance of AI applications should pay close attention to these advancements. By adopting innovative techniques like speculative decoding, they can improve the efficiency and reliability of their systems, ultimately leading to better user experiences and competitive advantages in the market.
Originally reported by NVIDIA Technical Blog.